Paper Summary - OSWorld-G
1. Introduction
This work aims to solve two challenges: Planning and Grounding.
1.2 Planning
Existing work (Aria-ui, OSWorld-G, Agent S, Agent S2, Aguvis) often pair a GUI grounding model with a planner. The planner determines an action proposal at each step, while the grounding model locates the target interface elements for interactions (e.g., click areas).
1.2 Grounding Training Problems
1.2.1 SFT Drawback
Existing grounding models (Aria-ui, JEDI, Os-altlas, Seeclick) predominantly rely on SFT, , which trains models to predict the exact center of target interface elements. This method struggles to generalize to complex and high-resolution scenarios.
Fundamentally, SFT introduces a misalignment with the task itself: any coordinate within the target element constitutes a valid interaction, yet SFT penalizes deviations from the center. It limits model flexibility, reduces robustness, and preventing the model from perceiving appropriate supervision signals.
Some recent works also use GRPO to train grounding model:
1.2.2 GRPO Method
Let grounding model output answer of input (screenshot & instruction). e.g.
1
2
3
4
5<thinking>
The user wants to filter search results. The search bar is at the top right,
and there is a funnel-shaped icon immediately to its right.
</thinking>
<answer>(1436, 340)</answer>Score with rules:
Reward Rule format reward Is output legal? Is format correct? click reward Is the output coordinate inside the golden bounding box? IoU reward How much a predicted bounding box (bbox) overlaps golden bbox; GRPO Update
1.2.3 GRPO Drawback
- format reward may be useless in sta, only the
thinkinglabel will be calculated in reward. So the content of thinking is meaningless even empty. - bbox reward may be useless
1.3 Experiment Settings
Planner Experiment
The traditional planner only predicts the next one step; This work’s solution: let planner generate k candidate actions and let judge select one to execute.
| K(Candidate Num) | OSWorld SR (50 step) | OSWorld SR (100 step) |
|---|---|---|
| 1 | 41.3% | 43.4% |
| 8 | 43.4% | 45.2% |
Grounding Experiment
Training grounding model by GRPO only with click reward.
Benchmark: ScreenSpot-Pro / ScreenSpot-V2 / OSWorld-G
| Reward | ScreenSpot-Pro | ScreenSpot-V2 | OSWorld-G |
|---|---|---|---|
| click | 50.1 | 92.4 | 67.7 |
| click + format | 46.9 | 93.2 | 67.0 |
| click + IoU | 42.2 | 89.2 | 59.2 |
| click + format + IoU | 44.5 | 89.3 | 59.9 |
2. Multimodal Agent Category
2.1. Two-stage GUI Agent
- Use advanced reasoning models as planner
- A separate grounding module
2.2 Native GUI Agent
A native GUI agent completes user tasks in an end-to-end manner.
Four main aspects are studied (Ui-tars):
- perception, interpreting the user interface to understand the current state;
- memory, storing knowledge and historical experiences to support making decisions;
- planning, analyzing the task and reflecting on progress to generate action proposals;
- action, performing atomic operations based on the action proposal to effectively progress toward the task goal.
3. GTA1
This work adopts a two-stage GUI agent framework composed of a planner and a grounding model.
3.1 Planning
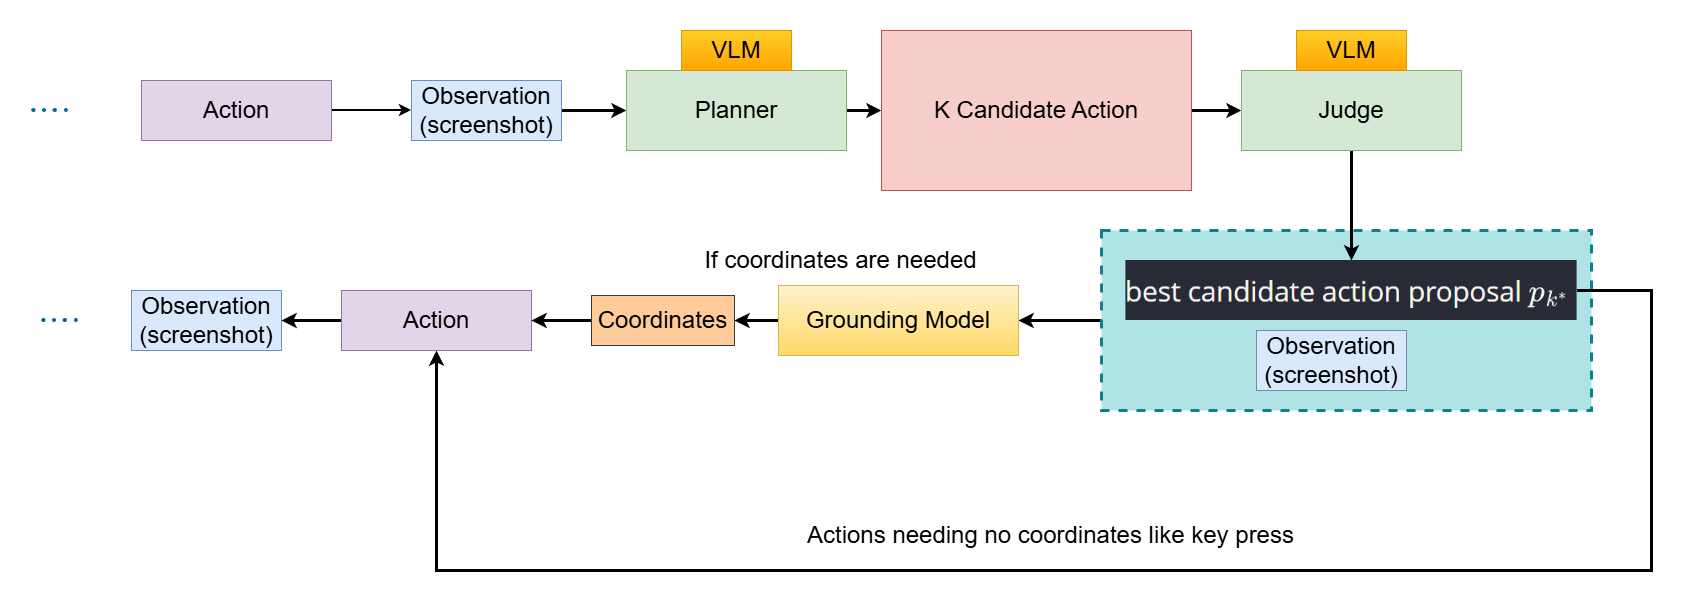
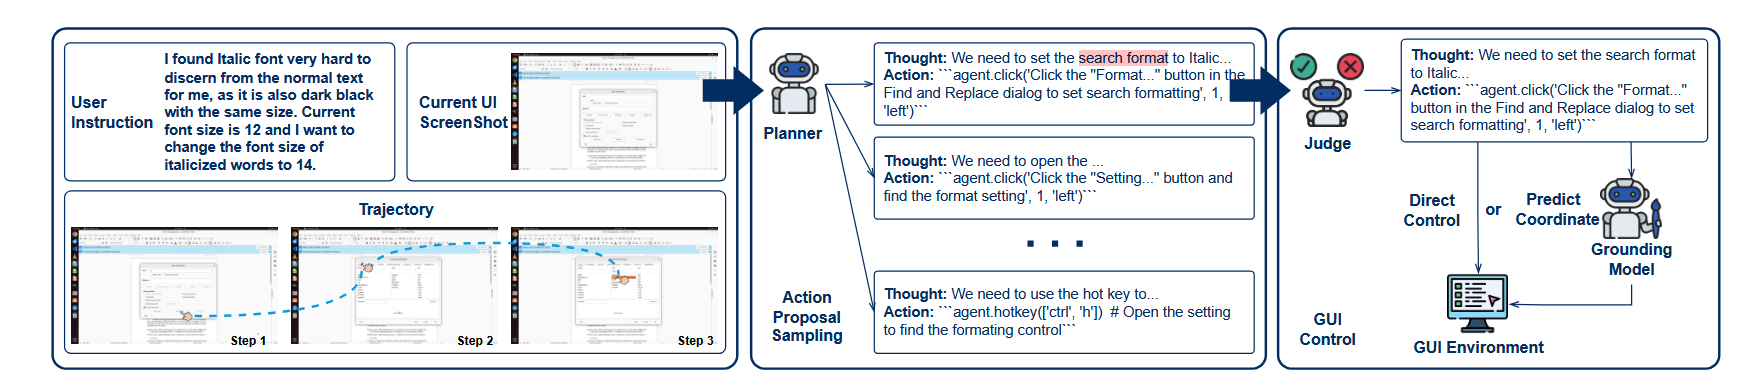
At each step of executing user instructions, sample K candidate action proposals, denoted as \(\{p_k\}_{k=1}^K\) where \(p_k\) presents a corresponding action. (e.g., clicking ‘the blue button’ or performing a keystroke).
Use a VLM as judge to evaluate the \(K\) candidates \(\{p_k\}_{k=1}^K\) based on their alignment with the user intent and the current GUI state.
The judge, which can be the planner model itself, picks the best candidate action proposal \(p_{k^*}\)
Grounding model takes the best candidate action proposal \(p_{k^*}\) and current screenshot \(s\) as input. Then grounding model outputs coordinates.
For non-coordinate-based actions (e.g., key presses or text input), the action can be executed directly without grounding.
3.2 Grounding
3.2.1 Data Preparation
Prepare training data:
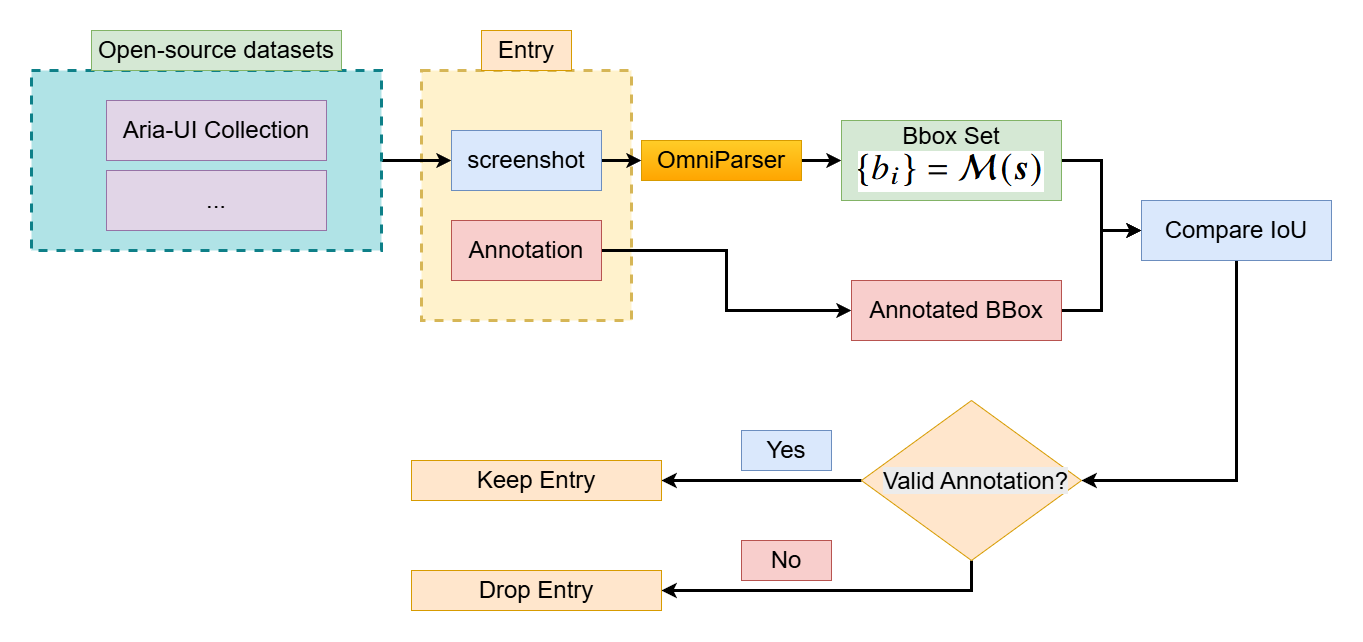
- Collect open-source datasets to train our model, e.g., the Aria-UI collection.
- These dataset’s bbox information comes from A11y or HTML parsers which may introduce noise.
- Cleanup the dataset: Using OmniParser, denoted as \(\mathcal M (\cdot)\), to detect all UI elements in screenshot \(s\), , resulting in a set of bounding boxes \(\{b_i\} = \{\mathcal M(s)\}\). Each \(b_i\) represents the bounding box of a detected UI element.
- Calculate the IoU of \(b_i\) and annotated bbox value. Drop the invalid entry.
3.3.2 GRPO
Base model comes from UI-TARS-7B and OpenCUA-32B.
4. Conclusion
- In two-stage GUI agent (separate planner and grounding model), the tradition agent structure only let ask planner rollout 1 next step action. GTA1 let planner generate 8 candidate actions.
- GTA1 is trained by GRPO with single
click rewardand outperform other models.