Paper Summary – SWE-smith
1. Introduction
However, the most effective agents still rely on proprietary LMs, as building open source LMs for SE remains bottlenecked by the lack of large-scale, high-quality training data. This article creates, SWE-smith, a novel pipeline for generating software engineering training data at scale.
SWE-bench:
- Find real bug
- Build up environment
- Verification
SWE-smith:
- Build up environment
- Create bug
- Verification
Contribution:
- 4 kinds bug generation strategies
- LM Generation
- Procedural Modification
- Combine Bugs
- Invert PRs
2. Main Work(Generate bug.diff)
2.1 Choose & Install Repository
SWE-smith requires Python projects with unit tests.
Filter Repository:
- Target repositories for the 5, 000 most downloaded packages listed in the Python Package Index (PyPI) as of November 18, 2024
- Sort the PyPI packages by GitHub stars
- Remove any PyPI package with less than 1, 000 stars, as well as all 12 SWE-bench test repositories from consideration.
Creaete corresponding image:
- Get the newest commit and SWE-agent to automatically attempt to install and run tests in 100 steps.
- Manually Check:
- Are the installation steps reasonable (without damaging the system environment) ?
- Are the test commands correct (have they actually run a complete test instead of a dummy run) ?
- Check if more than 80% of existing tests pass
- Create a Docker Image for the repository
2.2 Creating Task Instance Candidates
4 methods to create task instances:
- LM Generations
- Procedural Modification
- Combine Bugs
- Invert PRs (Most effective)
2.3 Execution-based Validation of Candidates
1 | git checkout origin-code |
2.4 Generating problem statements
End to End Demonstration
1 | 完整的端到端示例 |
3. Data Process & Tuning Model
3.1 Verification bug.diff is Effective
Run pre-gold test before applying patch, test log:
1
2
3
4
5
6
7
8
9
10
11
12test_get_loc_naive_dti_aware_str_deprecated PASSED
test_indexing_with_datetime_tz PASSED
test_indexing_fast_xs PASSED
test_consistency_with_tz_aware_scalar PASSED
test_indexing_with_datetimeindex_tz[setitem] PASSED
test_indexing_with_datetimeindex_tz[loc] PASSED
test_nanosecond_getitem_setitem_with_tz PASSED
test_getitem_str_slice_millisecond_resolution[DataFrame] PASSED
test_getitem_str_slice_millisecond_resolution[Series] PASSED
test_getitem_pyarrow_index[DataFrame] PASSED ← Notice ⚠️
test_getitem_pyarrow_index[Series] PASSED ← Notice ⚠️
Apply bug.diff file, then run test again
1
2
3
4
5
6
7
8
9
10
11test_get_loc_naive_dti_aware_str_deprecated PASSED
test_indexing_with_datetime_tz PASSED
test_indexing_fast_xs PASSED
test_consistency_with_tz_aware_scalar PASSED
test_indexing_with_datetimeindex_tz[setitem] PASSED
test_indexing_with_datetimeindex_tz[loc] PASSED
test_nanosecond_getitem_setitem_with_tz PASSED
test_getitem_str_slice_millisecond_resolution[DataFrame] PASSED
test_getitem_str_slice_millisecond_resolution[Series] PASSED
test_getitem_pyarrow_index[DataFrame] FAILED ← ❗
test_getitem_pyarrow_index[Series] FAILED ← ❗Create report.json
1
2
3
4
5
6
7
8
9
10
11
12
13{
"FAIL_TO_PASS": [
"pandas/tests/indexing/test_datetime.py::TestDatetimeIndex::test_getitem_pyarrow_index[DataFrame]",
"pandas/tests/indexing/test_datetime.py::TestDatetimeIndex::test_getitem_pyarrow_index[Series]"
],
"PASS_TO_PASS": [
"pandas/tests/indexing/test_datetime.py::TestDatetimeIndex::test_get_loc_naive_dti_aware_str_deprecated",
"pandas/tests/indexing/test_datetime.py::TestDatetimeIndex::test_indexing_with_datetime_tz",
"... total 9 ..."
],
"FAIL_TO_FAIL": [],
"PASS_TO_FAIL": []
}Failed Meaning Details FAIL_TO_PASS Pre-gold PASS → Post-gold FAIL 2 testcases disrupted by bug ✅ PASS_TO_PASS Pre-gold PASS → Post-gold PASS 9 testcases are not be affected ✅ FAIL_TO_FAIL Pre-gold PASS → Post-gold FAIL - PASS_TO_FAIL Pre-gold PASS → Post-gold FAIL - Judge Code (valid.py:144):
1
2
3
4if len(report[FAIL_TO_PASS]) == 0:
return {"status": "0_f2p"}
else:
return {"status": "1+_f2p"} # ✅ Valid Bug
3.2 Assemble SWE-bench Format Test Dataset
Read report and verify result (harness/gather.py :316-339)
1
2
3
4
5
6
7
8
9
10
11
12
13# read report.json
with open(path_results) as f:
results = json.load(f)
# 3 conditions needed
n_f2p = len(results[PASS_TO_FAIL])
n_p2p = len(results[PASS_TO_PASS])
# 1. not timeout
# 2. at least one testcase is disrupted
# 3. at least one testcase is passed
if KEY_TIMED_OUT in results or n_f2p == 0 or n_p2p == 0:
return SKIP # ← abortAssemble task_instance (harness/gather.py :341-353) :
1
2
3
4
5
6
7
8task_instance = {
"instance_id": subfolder, # e.g. "pandas-dev__pandas.95280573.pr_53652"
"patch": patch_content, # bug diff contents
"FAIL_TO_PASS": results[PASS_TO_FAIL], # from report.json, note the task_instance[f2p] is from result[p2f] beacuse of the rule of SWE-bench is f2p.
"PASS_TO_PASS": results[PASS_TO_PASS], # from report.json
"image_name": rp.image_name, # Docker Image name
"repo": rp.mirror_name, # GitHub repo name
}Create new Git branch (harness/gather.py :466-569) :
Create new branch for each valid instance on Github, then:
1
2
3
4
5
6
7git clone repo
git checkout main
git apply bug.diff # apply bug.diff
git commit -m "Bug Patch" # commit bug code
remove the testcases that will fail
git commit -m "Remove F2P Tests" # commit
Delete the testcase that will fail:
1
2
3
4
5
6
7f2p_test_files, _ = rp.get_test_files(task_instance)
if f2p_test_files:
for test_file in f2p_test_files:
os.remove(test_file_path) # delete the test that will fail
git add . && git commit -m "Remove F2P Tests"
Why delete this file ?
This way SWE-agent can find the tests need to be repaired by git diff.
git diff main -> deleted file -> bug position
1
2
3
4
5
6
7Agent git checkout → testcase not exist
Agent git log:
commit 1: "Bug Patch"
commit 2: "Remove Tests"
Agent inference: Deleted files in commit 2 is used to verify bug
Agent git checkout main -- test_xxx.py -> Restore testcase
...I don’t think it make sense.
Assemble all instances (harness/gather.py :269-273) :
1
2task_instances_path = LOG_DIR_TASKS / f"{run_id}.json"
json.dump(task_instances, f, indent=4)
3.3 Generate problem_statement by LLM (issue_gen/generate.py)
Input for LLM:
Demonstration :
Randomly select 2 genuine GitHub issues from the SWE-bench Verified as style references.
Patch (<patch> label) :
Content of bug.diff
test_output (<test_output> label) :
Testcases that failed in post-gold. (Introducing by bug.diff)
test_source_code (<test_source_code> label) :
Analyze the failed testcases’ source code by Python AST. Gather the full test source code.
LLM constrains (ig_v2.yaml) :
1 | instance: |- |
Generate problem_statement (generate.py :376-387) :
1 | if self.portkey_model: |
Extract statement (generate.py :398-401):
1 | problem_statements = [ |
Now the instances:
1 | { |
3.4 Collect traj by Expert Model ( Rejection Sampling Fine-Tuning) (_gen_trajs.sh)
SWE-smith aims to train a student model (Qwen 2.5 Coder 32B)
- If use student to solve the issues, the success rate is too low (~11%), and we cannot collect enough “successful trajectories”.
- Running with Claude 3.7 Sonnet (success rate ~36%) can collect a large number of high-quality “correct answer demonstrations”.
1 | sweagent run-batch \ |
1 | { |
1 | trajectories/<run_id>/ |
3.5 Filter Success Patches (swesmith/harness/eval.py)
1 | python -m swesmith.harness.eval \ |
1 | def run_evaluation(pred, instance, run_id, ...): |
1 | logs/run_evaluation/<run_id>/ |
Summary Report:
1 | { |
3.6 Trans .traj into OpenAI messages
Filter success trajectories (collect_trajs.py : 57-58) :
1
2
3
4report = json.loads(report_path.read_text())
is_resolved = report.get("resolved", False)
...
traj["resolved"] = is_resolvedFormat Conversion (utils.py : 81-111) :
Package
thoughtandactionas content:1
2
3
4
5
6
7
8
9
10
11def transform_traj_xml(traj):
for message in get_messages(traj):
if message["role"] == "assistant":
content = message["thought"]
content += "\n\n" + tool_call_to_action(message["tool_calls"])
elif message["role"] == "system":
content = SYSTEM_PROMPT
else: # tool / user
content = message["content"][0]["text"]
new_traj.append({"role": role, "content": content})
return {"messages": new_traj}e.g.
Unconverted .traj:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151{
"history": [
{
"role": "system",
"content": "SETTING: You are an autonomous programmer, and you're working directly in the command line with a special interface.",
"agent": "main",
"message_type": "system_prompt"
},
{
"role": "user",
"content": "We're currently solving the following issue within our repository. Here's the issue text:\nISSUE:\nSyntaxError: invalid syntax\nI'm running `missing_colon.py` as follows:\r\n\r\n```python\r\ndivision(23, 0)\r\n```\r\n\r\nbut I get the following error:\r\n\r\n```\r\n File \"/Users/fuchur/Documents/24/git_sync/swe-agent-test-repo/tests/./missing_colon.py\", line 4\r\n def division(a: float, b: float) -> float\r\n ^\r\nSyntaxError: invalid syntax\r\n```\n\n\nINSTRUCTIONS:\nNow, you're going to solve this issue on your own. Your terminal session has started and you're in the repository's root directory. You can use any bash commands or the special interface to help you. Edit all the files you need to and run any checks or tests that you want.\nRemember, YOU SHOULD ALWAYS INCLUDE EXACTLY ONE TOOL CALL/FUNCTION CALL PER RESPONSE.\nWhen you're satisfied with all of the changes you've made, you can submit your changes to the code base by simply running the submit command.\nNote however that you cannot use any interactive session commands (e.g. python, vim) in this environment, but you can write scripts and run them. E.g. you can write a python script and then run it with the python command.\n\nNOTE ABOUT THE EDIT COMMAND: Indentation really matters! When editing a file, make sure to insert appropriate indentation before each line!\n\nGENERAL IMPORTANT TIPS:\n\n1. If you run a command and it doesn't work, try running a different command. A command that did not work once will not work the second time unless you modify it!\n\n2. If you open a file and need to get to an area around a specific line that is not in the first 100 lines, say line 583, don't just use the scroll_down command multiple times. Instead, use the goto 583 command. It's much quicker.\n\n3. If the bug reproduction script requires inputting/reading a specific file, such as buggy-input.png, and you'd like to understand how to input that file, conduct a search in the existing repo code, to see whether someone else has already done that. Do this by running the command: find_file \"buggy-input.png\" If that doesn't work, use the linux 'find' command.\n\n4. Always make sure to look at the currently open file and the current working directory (which appears right after the currently open file). The currently open file might be in a different directory than the working directory! Note that some commands, such as 'create', open files, so they might change the current open file.\n\n5. When editing files, it is easy to accidentally to write code with incorrect indentation or make other mistakes. Always check the code after you issue an edit to make sure that it reflects what you wanted to accomplish. If it didn't, issue another command to fix it.\n\n6. When editing files, first explain the code you want to edit and why it is causing the problem. Then explain the edit you want to make and how it fixes the problem. Explain how the edit does not break existing functionality.\n\n7. Do not try to install any packages with `pip`, `conda`, or any other way. This will usually not work. If the environment is not set up correctly, try to fix the issue without executing python code or running any tests that require the package installed.\n\nSTRATEGY:\n\n1. Locate relevant files using the find and search commands, then read the code related to the issue.\n\n2. Try to replicate the bug that the issues discusses.\n If the issue includes code for reproducing the bug, we recommend that you re-implement that in your environment, and run it to make sure you can reproduce the bug.\n Then start trying to fix it.\n\n If the bug reproduction script does not print anything when it successfully runs, we recommend adding a print(\"Script completed successfully, no errors.\") command at the end of the file,\n so that you can be sure that the script indeed ran fine all the way through.\n\n3. Use the `edit` command to perform edits on the files that cause the issue.\n\n4. When you think you've fixed the bug, re-run the bug reproduction script to make sure that the bug has indeed been fixed.\n\n5. Create additional tests to verify the fix in a style similar to the existing reproduction script. In particular, make sure to test edge cases.\n If you find any issues, go back to the file you edited and perform further edits.\n\n(Open file: n/a)\n(Current directory: /SWE-agent__test-repo)\nbash-$",
"agent": "main",
"message_type": "observation"
},
{
"role": "assistant",
"content": "The `SyntaxError` in `missing_colon.py` is likely due to a missing colon at the end of the function definition line. To resolve this, we need to locate and edit the file to add the missing colon at the end of the function definition. Let's start by searching for `missing_colon.py` to locate it.",
"thought": "The `SyntaxError` in `missing_colon.py` is likely due to a missing colon at the end of the function definition line. To resolve this, we need to locate and edit the file to add the missing colon at the end of the function definition. Let's start by searching for `missing_colon.py` to locate it.",
"action": "find_file missing_colon.py",
"agent": "main",
"tool_calls": [
{
"function": {
"arguments": "{\"file_name\":\"missing_colon.py\"}",
"name": "find_file"
},
"id": "call_PbWErNIge3YTrli3fiVvmIid",
"type": "function"
}
],
"message_type": "action"
},
{
"role": "tool",
"content": "Found 1 matches for \"missing_colon.py\" in /SWE-agent__test-repo:\r\n/SWE-agent__test-repo/tests/missing_colon.py\n(Open file: n/a)\n(Current directory: /SWE-agent__test-repo)\nbash-$",
"agent": "main",
"message_type": "observation",
"tool_call_ids": [
"call_PbWErNIge3YTrli3fiVvmIid"
]
},
{
"role": "assistant",
"content": "We have found the `missing_colon.py` file in the `tests` directory. Let's open it to review and make necessary edits.",
"thought": "We have found the `missing_colon.py` file in the `tests` directory. Let's open it to review and make necessary edits.",
"action": "open \"tests/missing_colon.py\"",
"agent": "main",
"tool_calls": [
{
"function": {
"arguments": "{\"path\":\"tests/missing_colon.py\"}",
"name": "open"
},
"id": "call_upNLxh7rBcDH9w5XiNdoAS0I",
"type": "function"
}
],
"message_type": "action"
},
{
"role": "tool",
"content": "[File: tests/missing_colon.py (10 lines total)]\r\n1:#!/usr/bin/env python3\r\n2:\r\n3:\r\n4:def division(a: float, b: float) -> float\r\n5: return a/b\r\n6:\r\n7:\r\n8:if __name__ == \"__main__\":\r\n9: print(division(123, 15))\r\n10:\n(Open file: /SWE-agent__test-repo/tests/missing_colon.py)\n(Current directory: /SWE-agent__test-repo)\nbash-$",
"agent": "main",
"message_type": "observation",
"tool_call_ids": [
"call_upNLxh7rBcDH9w5XiNdoAS0I"
]
},
{
"role": "assistant",
"content": "The issue is indeed caused by a missing colon at the end of the function definition line for `division`. We should add a colon at the end of the `def division(a: float, b: float) -> float` line. Let's fix this by editing the file.",
"thought": "The issue is indeed caused by a missing colon at the end of the function definition line for `division`. We should add a colon at the end of the `def division(a: float, b: float) -> float` line. Let's fix this by editing the file.",
"action": "edit 'def division(a: float, b: float) -> float' 'def division(a: float, b: float) -> float:'",
"agent": "main",
"tool_calls": [
{
"function": {
"arguments": "{\"search\":\"def division(a: float, b: float) -> float\",\"replace\":\"def division(a: float, b: float) -> float:\"}",
"name": "edit"
},
"id": "call_hIiDKXAXZl4qMHV6RRXvil4u",
"type": "function"
}
],
"message_type": "action"
},
{
"role": "tool",
"content": "Text replaced. Please review the changes and make sure they are correct:\r\n\r\n1. The edited file is correctly indented\r\n2. The edited file does not contain duplicate lines\r\n3. The edit does not break existing functionality\r\n\r\nEdit the file again if necessary.\r\n[File: /SWE-agent__test-repo/tests/missing_colon.py (10 lines total)]\r\n1:#!/usr/bin/env python3\r\n2:\r\n3:\r\n4:def division(a: float, b: float) -> float:\r\n5: return a/b\r\n6:\r\n7:\r\n8:if __name__ == \"__main__\":\r\n9: print(division(123, 15))\r\n10:\n(Open file: /SWE-agent__test-repo/tests/missing_colon.py)\n(Current directory: /SWE-agent__test-repo)\nbash-$",
"agent": "main",
"message_type": "observation",
"tool_call_ids": [
"call_hIiDKXAXZl4qMHV6RRXvil4u"
]
},
{
"role": "assistant",
"content": "The missing colon has been added successfully. Now, we can run the script to ensure that the SyntaxError is resolved.",
"thought": "The missing colon has been added successfully. Now, we can run the script to ensure that the SyntaxError is resolved.",
"action": "python tests/missing_colon.py",
"agent": "main",
"tool_calls": [
{
"function": {
"arguments": "{\"command\":\"python tests/missing_colon.py\"}",
"name": "bash"
},
"id": "call_5O339epJ3rKjEal3Kuvpj9bM",
"type": "function"
}
],
"message_type": "action"
},
{
"role": "tool",
"content": "8.2\n(Open file: /SWE-agent__test-repo/tests/missing_colon.py)\n(Current directory: /SWE-agent__test-repo)\nbash-$",
"agent": "main",
"message_type": "observation",
"tool_call_ids": [
"call_5O339epJ3rKjEal3Kuvpj9bM"
]
},
{
"role": "assistant",
"content": "The script ran successfully, printing the result `8.2`, and the syntax error is resolved. Now that the fix is verified, let's submit our changes.",
"thought": "The script ran successfully, printing the result `8.2`, and the syntax error is resolved. Now that the fix is verified, let's submit our changes.",
"action": "submit",
"agent": "main",
"tool_calls": [
{
"function": {
"arguments": "{}",
"name": "submit"
},
"id": "call_6zuFhIfpOAi1jAiD2QHMmh6S",
"type": "function"
}
],
"message_type": "action"
},
{
"role": "tool",
"content": "\r\ndiff --git a/tests/missing_colon.py b/tests/missing_colon.py\r\nindex 20edef5..5857437 100755\r\n--- a/tests/missing_colon.py\r\n+++ b/tests/missing_colon.py\r\n@@ -1,7 +1,7 @@\r\n #!/usr/bin/env python3\r\n \r\n \r\n-def division(a: float, b: float) -> float\r\n+def division(a: float, b: float) -> float:\r\n return a/b\r\n \r\n \r\n\n(Open file: /SWE-agent__test-repo/tests/missing_colon.py)\n(Current directory: /SWE-agent__test-repo)\nbash-$",
"agent": "main",
"message_type": "observation",
"tool_call_ids": [
"call_6zuFhIfpOAi1jAiD2QHMmh6S"
]
}
]
}transform_traj_xml;
Converted .jsonl:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17{
"messages": [
{"role": "system", "content": "You are an autonomous programmer..."},
{"role": "user", "content": "ISSUE: SyntaxError...\nINSTRUCTIONS..."},
{"role": "assistant", "content": "Let's search...", "tool_calls": [{"function": {"name": "find_file", "arguments": "..."}}]},
{"role": "tool", "content": "Found 1: .../missing_colon.py", "tool_call_id": "..."},
{"role": "assistant", "content": "Let's open...", "tool_calls": [{"function": {"name": "open", "arguments": "..."}}]},
{"role": "tool", "content": "[File: missing_colon.py...]", "tool_call_id": "..."},
{"role": "assistant", "content": "Fix colon...", "tool_calls": [{"function": {"name": "edit", "arguments": "..."}}]},
{"role": "tool", "content": "Text replaced...", "tool_call_id": "..."},
{"role": "assistant", "content": "Run script...", "tool_calls": [{"function": {"name": "bash", "arguments": "..."}}]},
{"role": "tool", "content": "8.2", "tool_call_id": "..."},
{"role": "assistant", "content": "Submit...", "tool_calls": [{"function": {"name": "submit", "arguments": "{}"}}]}
],
"resolved": true,
"instance_id": "..."
}
3.7 Full Tuning
train/run/ft_torchtune.py
configs/train/full_ft_qwen_32b.yml
1 | modal run swesmith/train/run/ft_torchtune.py \ |
1 |
|
Train config (full_ft_qwen_32b.yml) :
1 | model: |
| message # | role | content | Calculate Loss? |
|---|---|---|---|
| system user |
“You are a helpful assistant…” “I’ve uploaded a python code repository…” |
||
| 1 | assistant | “I’ll help you…\n<function=bash>…” | ✅ |
| 2 | user | “OBSERVATION:\n/testbed/pandas/…” | |
| 3 | assistant | “The PR description mentions…\n<function=bash>” | ✅ |
| 4 | user | “OBSERVATION:\n6070 if keyarr…” | |
| 5 | assistant | “I see the issue…Let me create a script… | ✅ |
| 6 | user | “OBSERVATION:\nFile created successfully.” | |
| 7 | assistant | “Now let me run the script… | ✅ |
| 8 | user | “OBSERVATION:\nAttributeError: ’Inde… | |
| 9 | assistant | “Confirmed. Now I’ll fix… | ✅ |
| 10 | user | “OBSERVATION:\nCommand executed | |
| 11 | assistant | “Let me rerun…\n< | ✅ |
| 12 | user | “OBSERVATION:\n values…” | |
| 13 | assistant | “The fix works. Let me submit.\n<function=submit>” | ✅ |
e.g.
1 | assistant: "I see the issue. Let me create a script. |
1 | Model Input: "...OBSERVATION:\nFile created.\n I see the issue. Let me create" |
3.7.1 train_on_input: False
1 | system: You are a helpful assistant that can interact with a computer... |
❌If train_on_input: True, the Model need to study too much meaning less information:
1 | system: You▁are▁a▁helpful▁assistant... ← ✅ calculate loss |
✅train_on_input: False: Only calculate Loss the assistant’s:
1 | system: You▁are▁a▁helpful▁assistant... ❌ mask |
3.7.2 Loss Between Steps (Teacher Forcing)
traj:
1 | [0] system: "You are a helpful assistant..." |
tokenization:
$$ \text{sys}_0,\text{user}_0,\textcolor{green}{assistant}_0 ,\text{user}_1,\textcolor{green}{assistant}_1,\text{user}_2,\textcolor{green}{assistant}_3,\text{user}_3,\textcolor{green}{assistant}_3,\text{user}_4,\textcolor{green}{assistant}_4 $$
Causal Attention Mask:
1 | sys₀ user₀ assist₀ user₁ assist₁ user₂ assist₂ |
3.7.3 packed: False
1 | packed: False |
Means that SWE-smith trains the model with serial method.
No concatenation !
If concatenated, the latter one’s tokens can see all tokens of the one.
4. Supplements
4.1 Flowchart
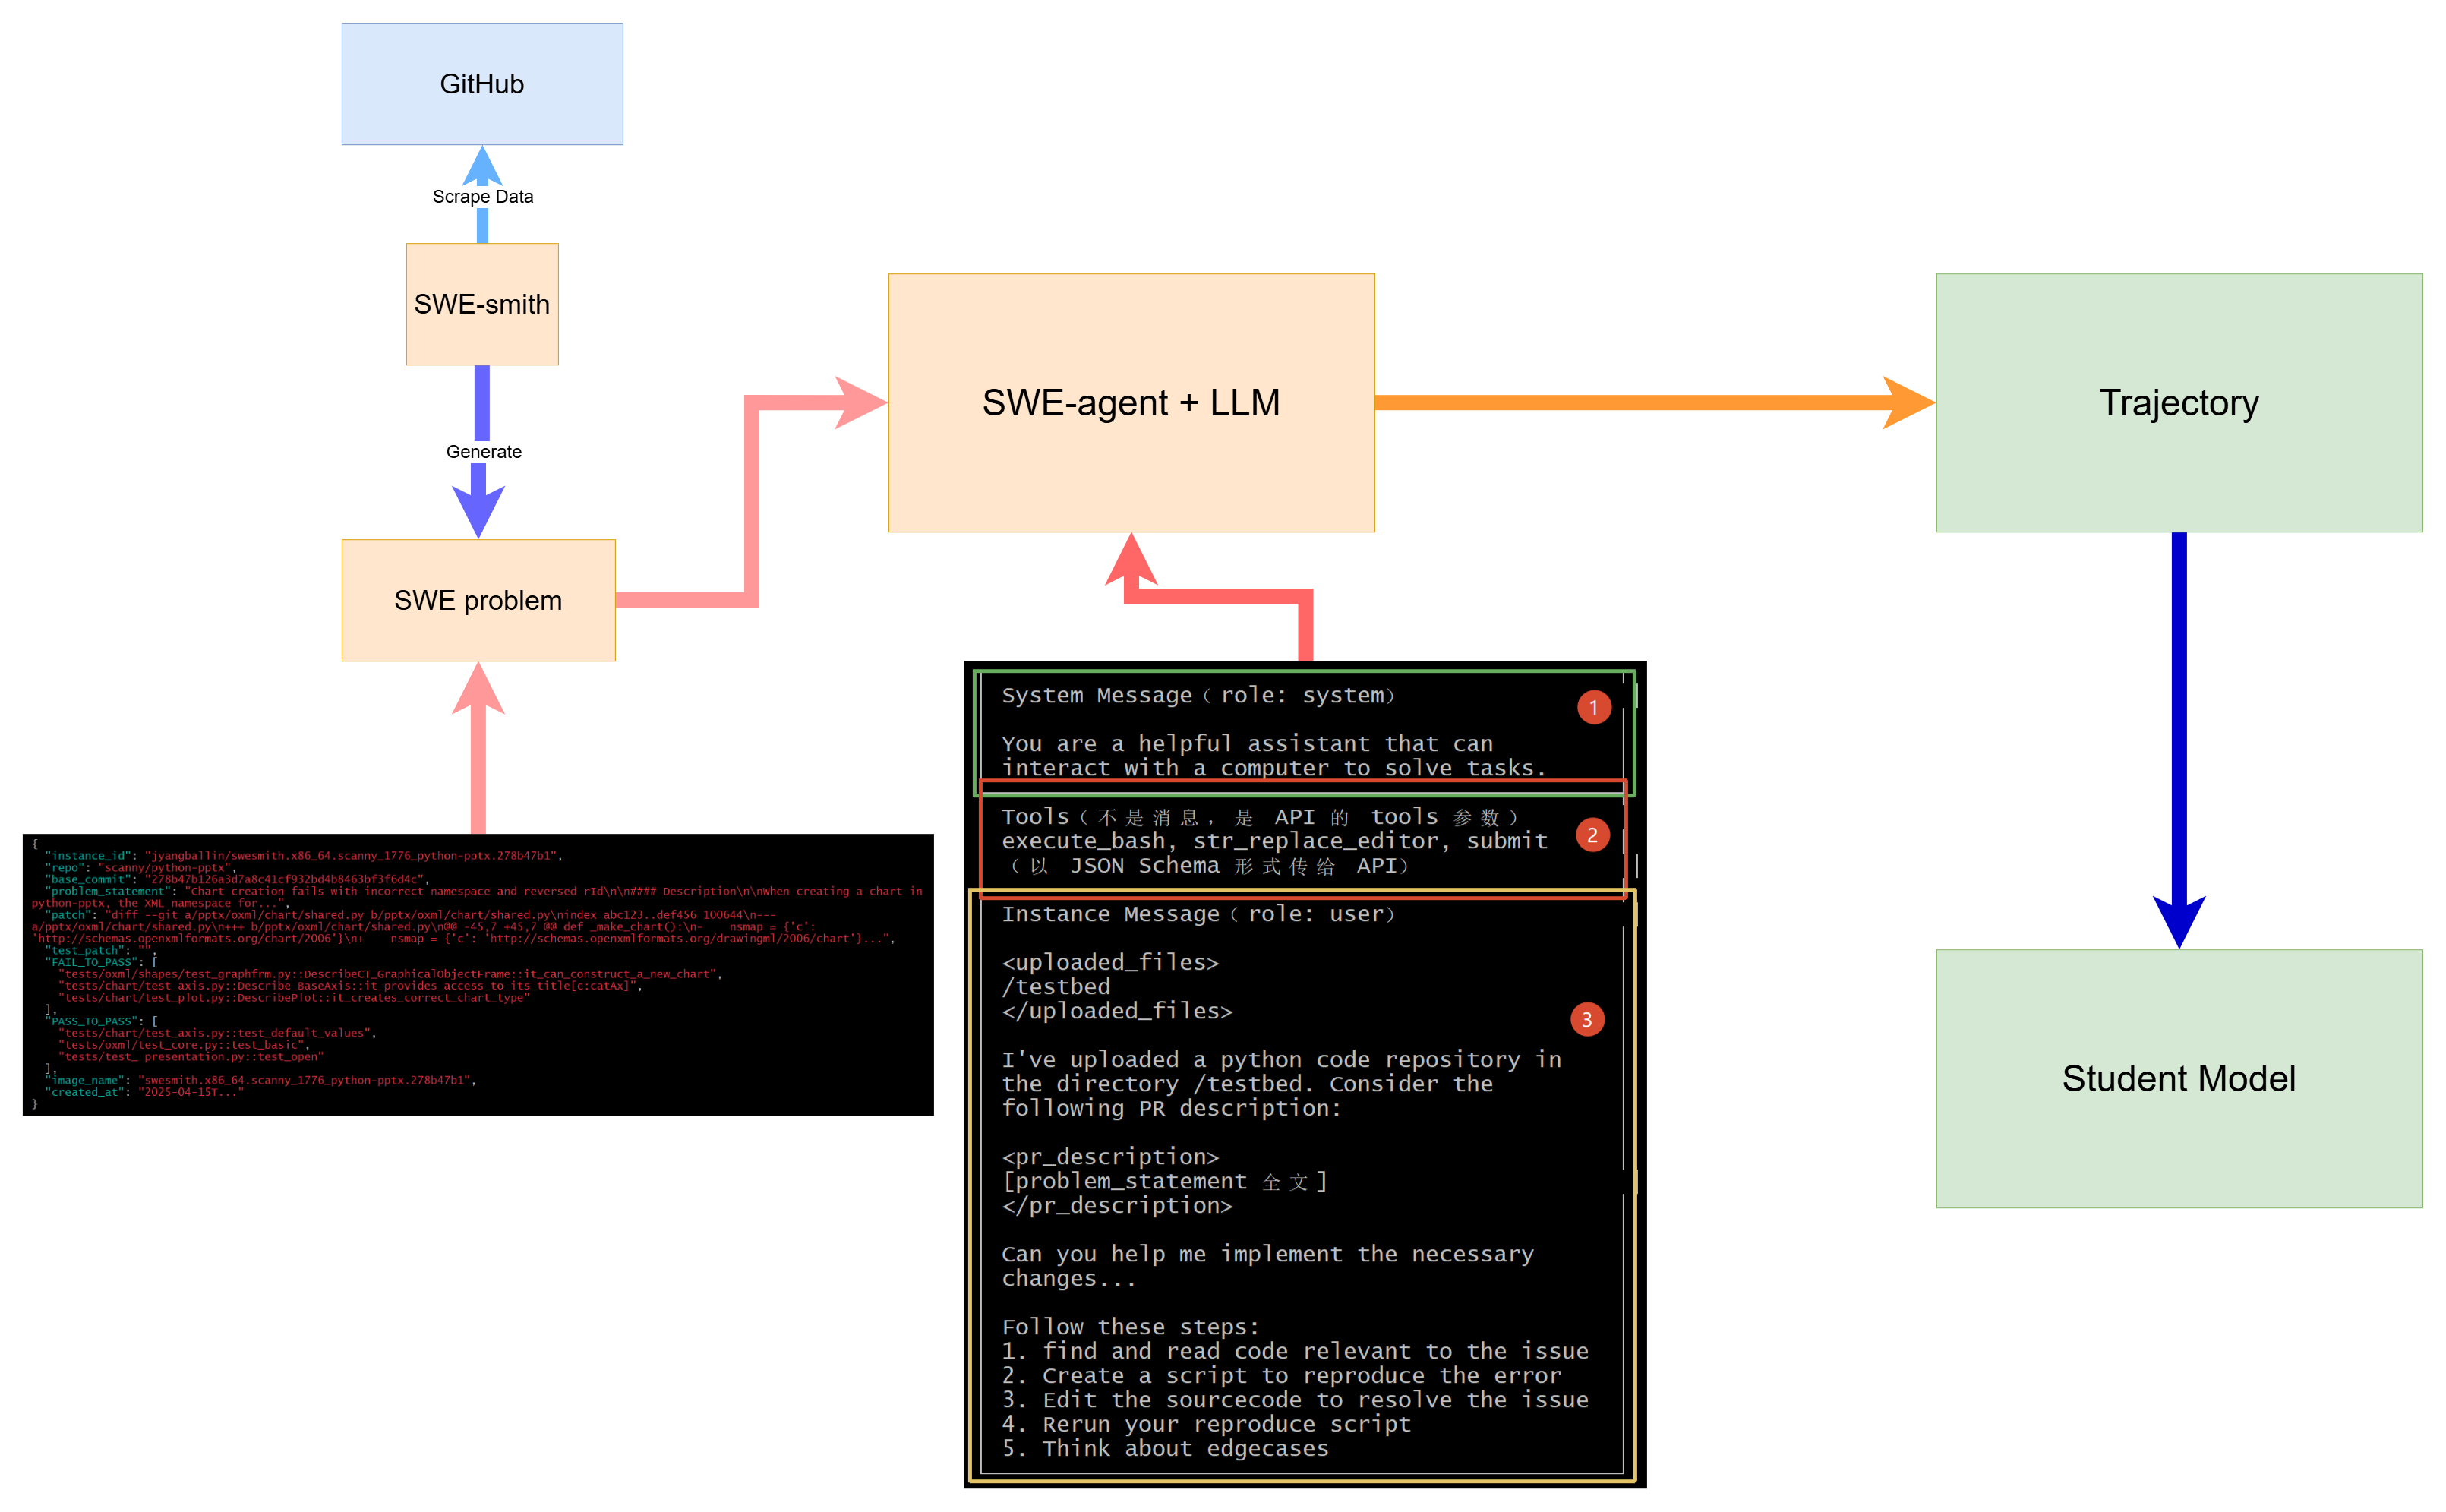
4.2 SWE
2025 SWE-Bench Verified
| Model | Pass@1 | ||
|---|---|---|---|
| Scale-SWE-Agent (30B) | 64% | 100K 真实 PR trajectory | 纯 SFT |
| CoderForge-Preview-32B | 59.4% | 多源 trajectory 混合 | 纯 SFT |
| NVIDIA Nemotron (14B) | 43.1% | SWE-Fixer+Smith 混合 | SFT → GRPO RL |
| SWE-agent-LM-32B | 40.2% | 5,016 条 SWE-smith trajectory | 纯 SFT |
| SWE-RL (Llama 3.3 70B) | 41% | 11M PR(不含 trajectory) | 纯离线 RL(GRPO) |
| SWE-Gym 32B + Verifier | 32% | 491 条 trajectory | SFT + Verifier |
| RepoForge-8B | 17.4% | 7,304 条自制 trajectory | SFT → RL |
| Method | trajectory ? | Representative | Description |
|---|---|---|---|
| 纯 SFT | ✅ | SWE-smith, Scale-SWE, CoderForge | teacher sample trajectories, SFT student |
| SFT → RL | ✅ | Nemotron, RepoForge | SFT + RL |
| 纯 RL(离线) | ❌ | SWE-RL | Use Text-Similarity to RL |
| SFT → Verifier | ✅ | SWE-Gym | SFT 一个生成器 + 训练一个打分器 |
Q: teacher sample 后, SFT自己, 会不会效果更好?